> For the complete documentation index, see [llms.txt](https://docs.bluerock.io/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.bluerock.io/bluerock-documentation-2.7.0-beta/bluerock-dashboard/agent-to-model-analytics.md).
# Agent-to-Model Analytics
### Overview
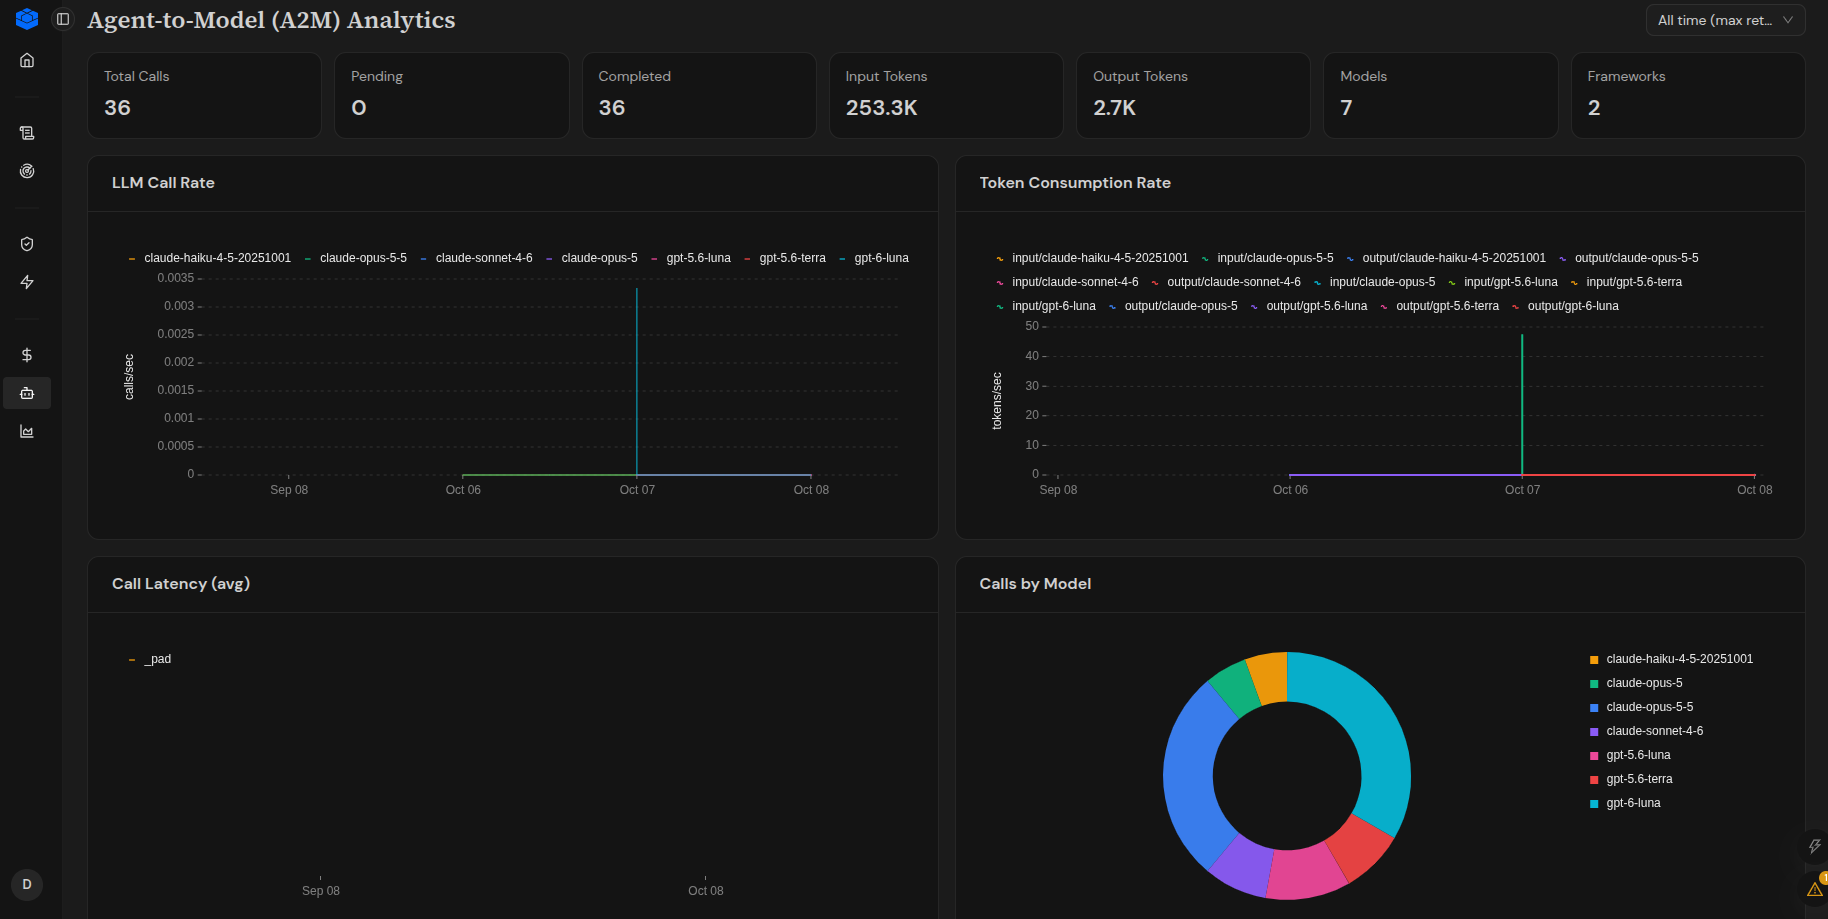
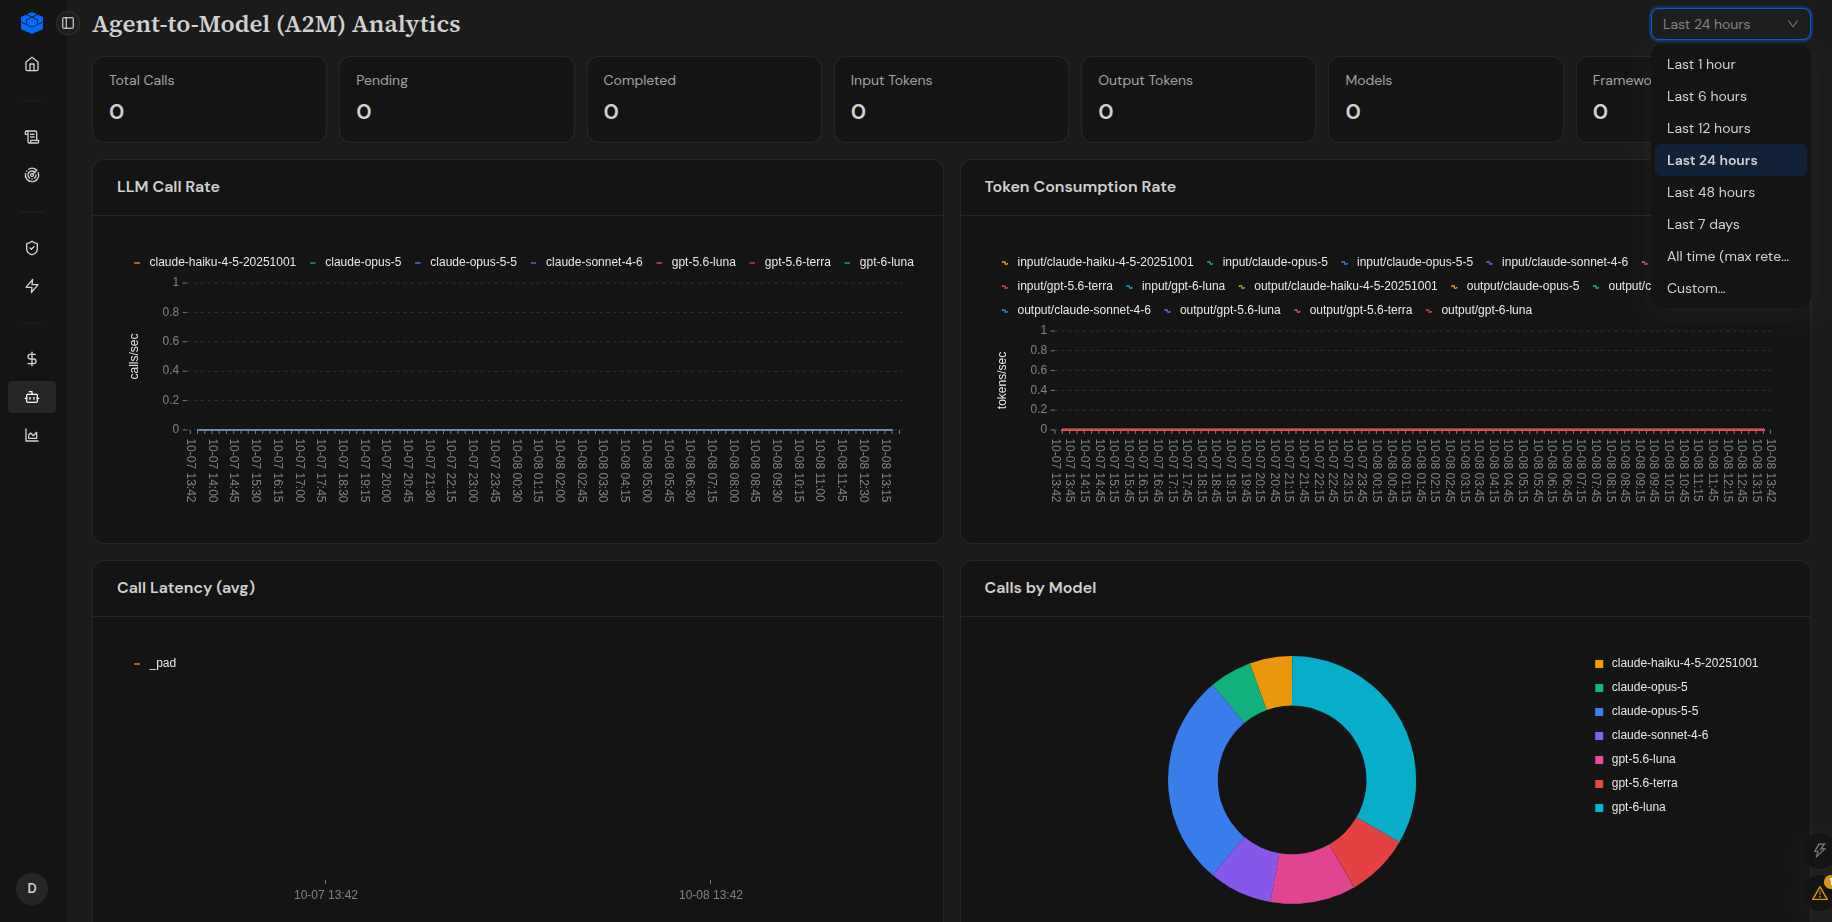
The **Agent-to-Model (A2M) Analytics** dashboard provides operational insights into interactions between AI agents and Large Language Models (LLMs).
It enables administrators to monitor:
* LLM request volume
* Token consumption
* Model utilization
* Framework distribution
* Call performance over time
Unlike the **Cost Management** dashboard, which focuses on cost and token usage, the **A2M Analytics** dashboard emphasizes request volume, latency, model utilization, and operational performance.
The dashboard helps identify usage trends, evaluate model performance, and monitor AI workload activity.
***
#### Access A2M Analytics
1. From the BlueRock Dashboard, select **Agent-to-Model Analytics** from the navigation menu.
2. The **Agent-to-Model Analytics** dashboard opens.
***
#### Dashboard Panels
The A2M Analytics dashboard provides summary metrics and charts for monitoring LLM activity.
#### Summary Metrics
The summary cards at the top of the dashboard provide an overview of LLM activity.
| Metric | Description |
| ----------------- | ---------------------------------------------------------------------- |
| **Total Calls** | Total number of LLM calls. |
| **Pending** | Number of LLM calls currently pending. |
| **Completed** | Number of completed LLM calls. |
| **Input Tokens** | Number of input tokens processed. |
| **Output Tokens** | Number of output tokens generated. |
| **Models** | Number of models used during the selected time range. |
| **Frameworks** | Number of frameworks or providers used during the selected time range. |
***
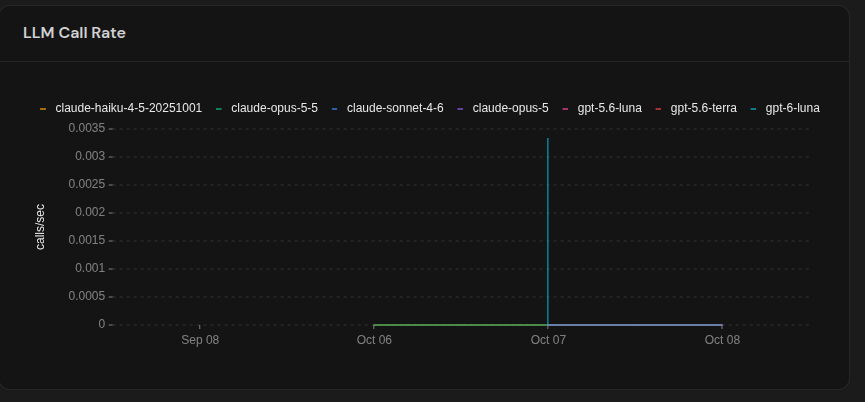
### LLM Call Rate
The **LLM Call Rate** panel displays the rate of LLM requests over time for each model.
Use this panel to monitor request activity and identify changes or spikes in workload.
***
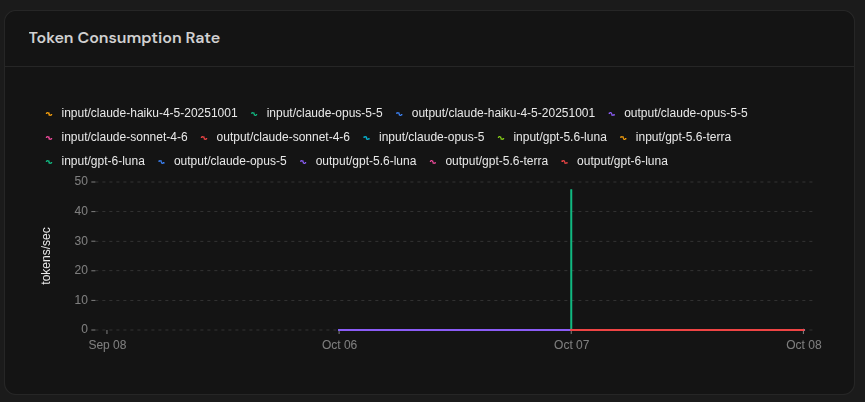
### Token Consumption Rate
The **Token Consumption Rate** panel displays input and output token usage over time across language models.
Use this panel to analyze token consumption patterns and changes in usage over time.
***
### Call Latency (Average)
The **Call Latency (Average)** panel displays the average response time for LLM requests.
Use this panel to monitor model response performance and identify latency trends.
***
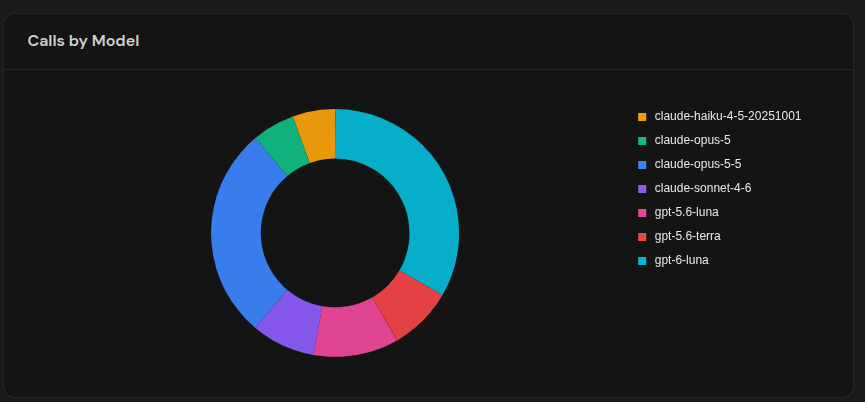
### Calls by Model
The **Calls by Model** panel displays the distribution of LLM requests across the models being used.
Use this panel to understand model utilization and compare request activity across models.
***
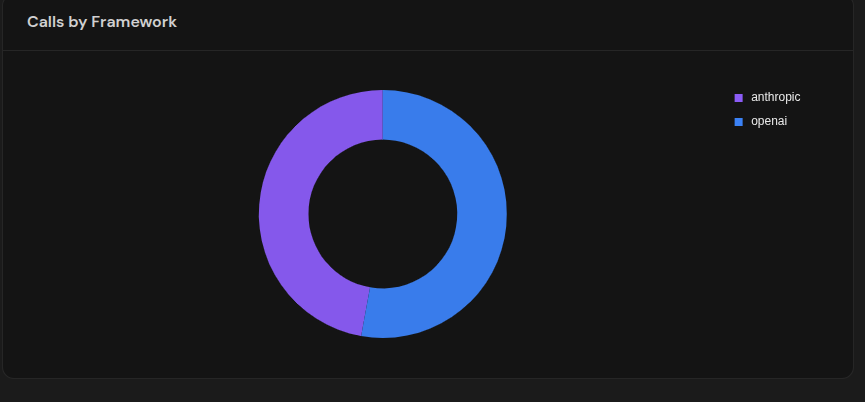
### Calls by Framework
The **Calls by Framework** panel displays the distribution of LLM requests across supported AI frameworks or providers.
The available frameworks or providers depend on the telemetry received by BlueRock.
***
## Time Filter
The **Time Filter** allows you to select the time range used for the dashboard metrics and charts.
1. Select the **Time Filter** in the upper-right corner of the dashboard.
2. Select the required time range.
3. The dashboard updates the displayed metrics and charts for the selected period.
***
## Interpreting A2M Analytics
Use the dashboard panels together to understand LLM activity:
* **Summary Metrics** provide an overall view of current LLM activity.
* **LLM Call Rate** shows request activity over time.
* **Token Consumption Rate** shows changes in input and output token usage.
* **Call Latency (Average)** helps monitor response performance.
* **Calls by Model** shows model utilization.
* **Calls by Framework** shows the distribution of activity across supported frameworks or providers.
* **Time Filter** allows you to analyze activity for the required period.
***
{% hint style="info" %}
**Note:** The metrics and charts displayed in A2M Analytics depend on the telemetry available from the connected AI agents, frameworks, and LLM providers.
{% endhint %}
***
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.bluerock.io/bluerock-documentation-2.7.0-beta/bluerock-dashboard/agent-to-model-analytics.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.